Ye Tian 田野
tytian@outlook.com Google Scholar LinkedIn
I am Head of Foundation Models at Noitom Robotics, where I lead pretraining, post-training, and scaling research for VLMs, VLAs, and world models.
Previously, I led the team for embodied reasoning and planning models (S2) and agents at Tencent Robotics X and concurrently headed the Embodied Human-Robot Interaction Research Center at Futian Laboratory (具身智能广东省实验室). Before that, at Tencent AI Lab, I worked on post-training and reinforcement learning for Tencent HY foundation models, as well as large-scale self-play reinforcement learning for Tencent Jueyi (LuckyJ). Earlier, I researched video understanding and generation at Verb Surgical (Mountain View, CA), a surgical robotics joint venture between Google Life Sciences (Verily) and Johnson & Johnson.
My research interests include pretraining, scaling, and generalization of embodied foundation models, reinforcement learning, and language model reasoning and self-improvement.
I received my master’s degree in Robotics from Johns Hopkins University, and my bachelor’s degree from Beijing Jiaotong University. I was also a visiting scholar at the University of Maryland, Baltimore, and an exchange student at UC San Diego.
Current Work
Noitom Robotics · The Information 50 2026 — No. 1 in Asia
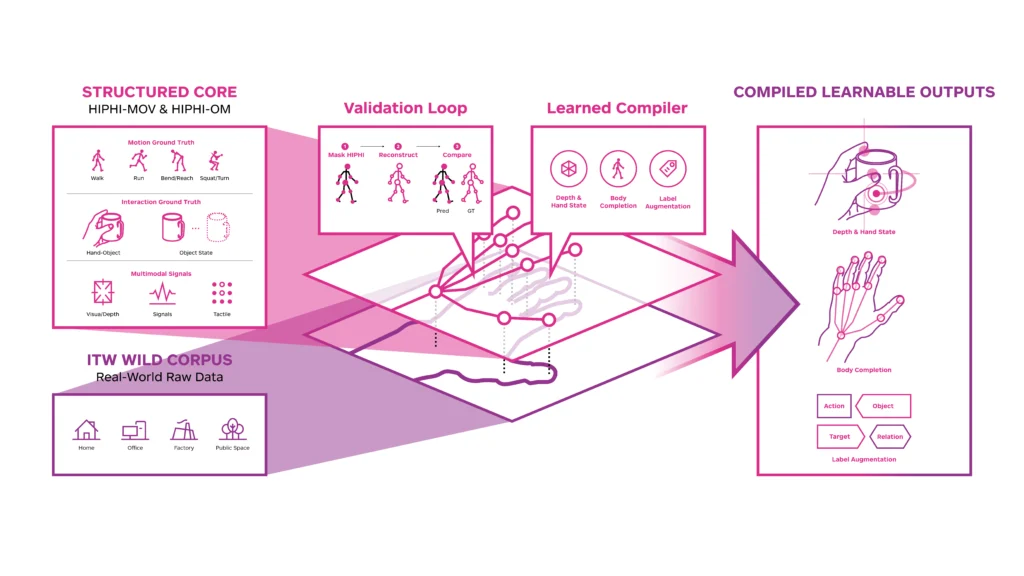
I have scaled embodied model pretraining to over 100,000 hours of human behavior data, studying how data scale and composition, action representations, and training methods affect robot manipulation and generalization.
We build an egocentric video pipeline for action and semantic annotation to support large-scale pretraining of embodied foundation models.
Previous Work
-
TAIROS: embodied planning models
Tencent Robotics X
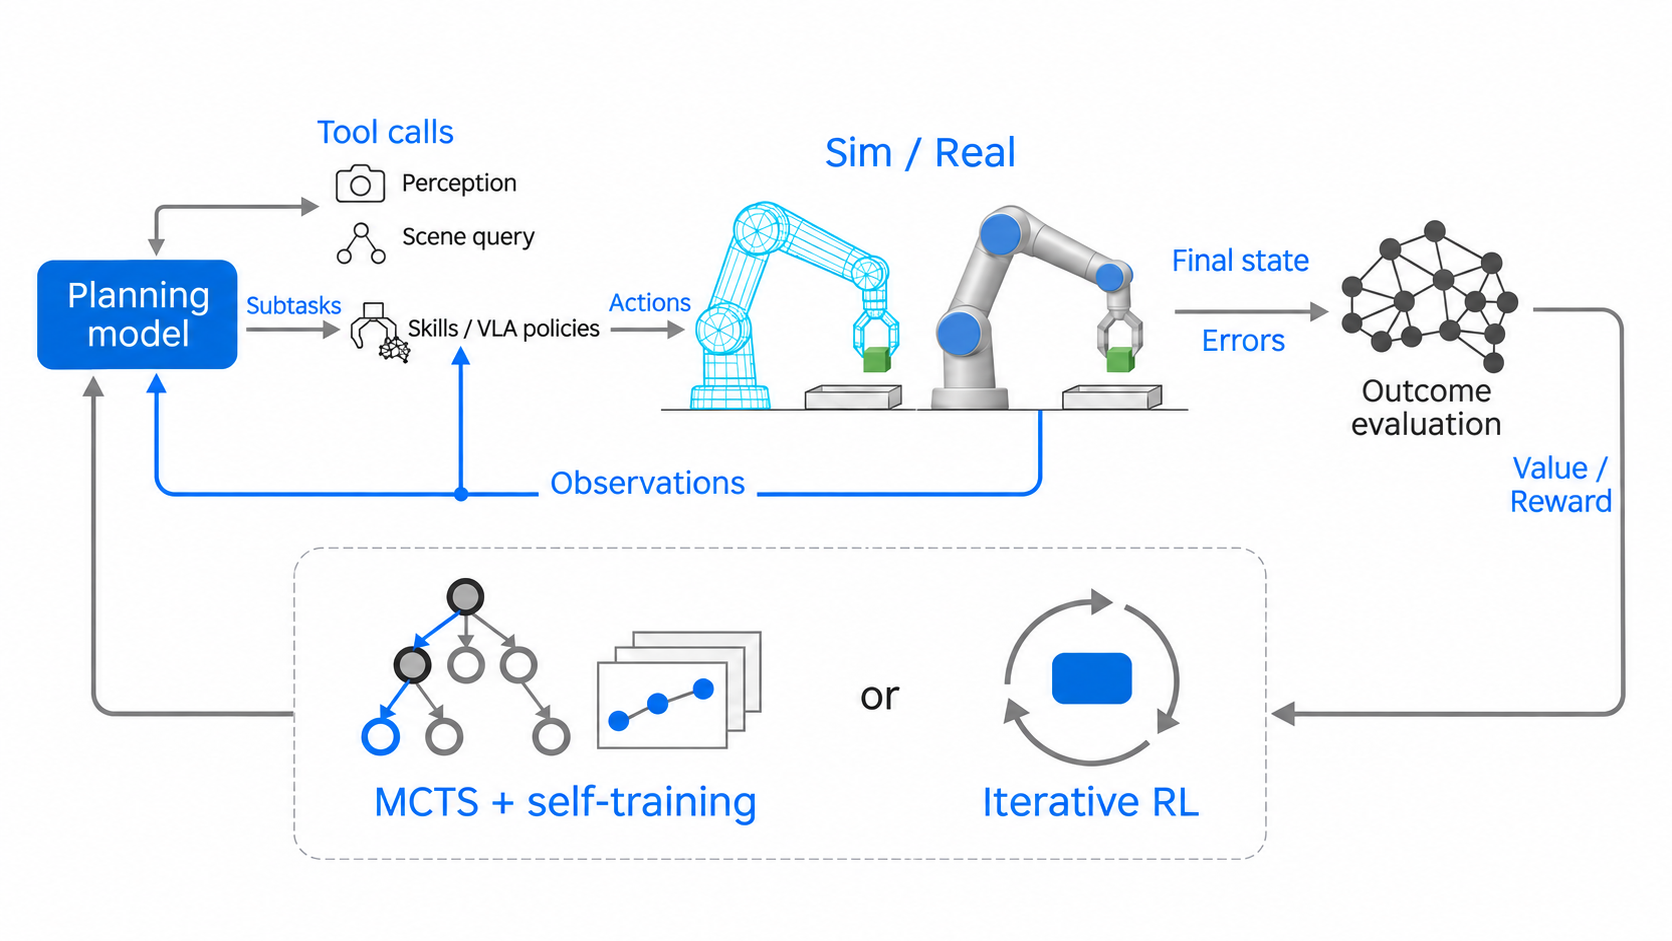
The TAIROS planning model supports reasoning, task decomposition, tool use, and multi-turn interaction for long-horizon robot tasks. Related research explored RL and MCTS for embodied agent planning and decision-making. The planning model was showcased at WAIC 2025 and integrated with Unitree’s platform through the Tencent–Unitree strategic partnership.
-
Tencent HY: foundation model post-training and RL
Tencent AI Lab
I contributed to Tencent HY, developing reinforcement learning pipelines for post-training and training foundation models.
-
AlphaLLM: LLM reasoning and self-improvement
Tencent AI Lab
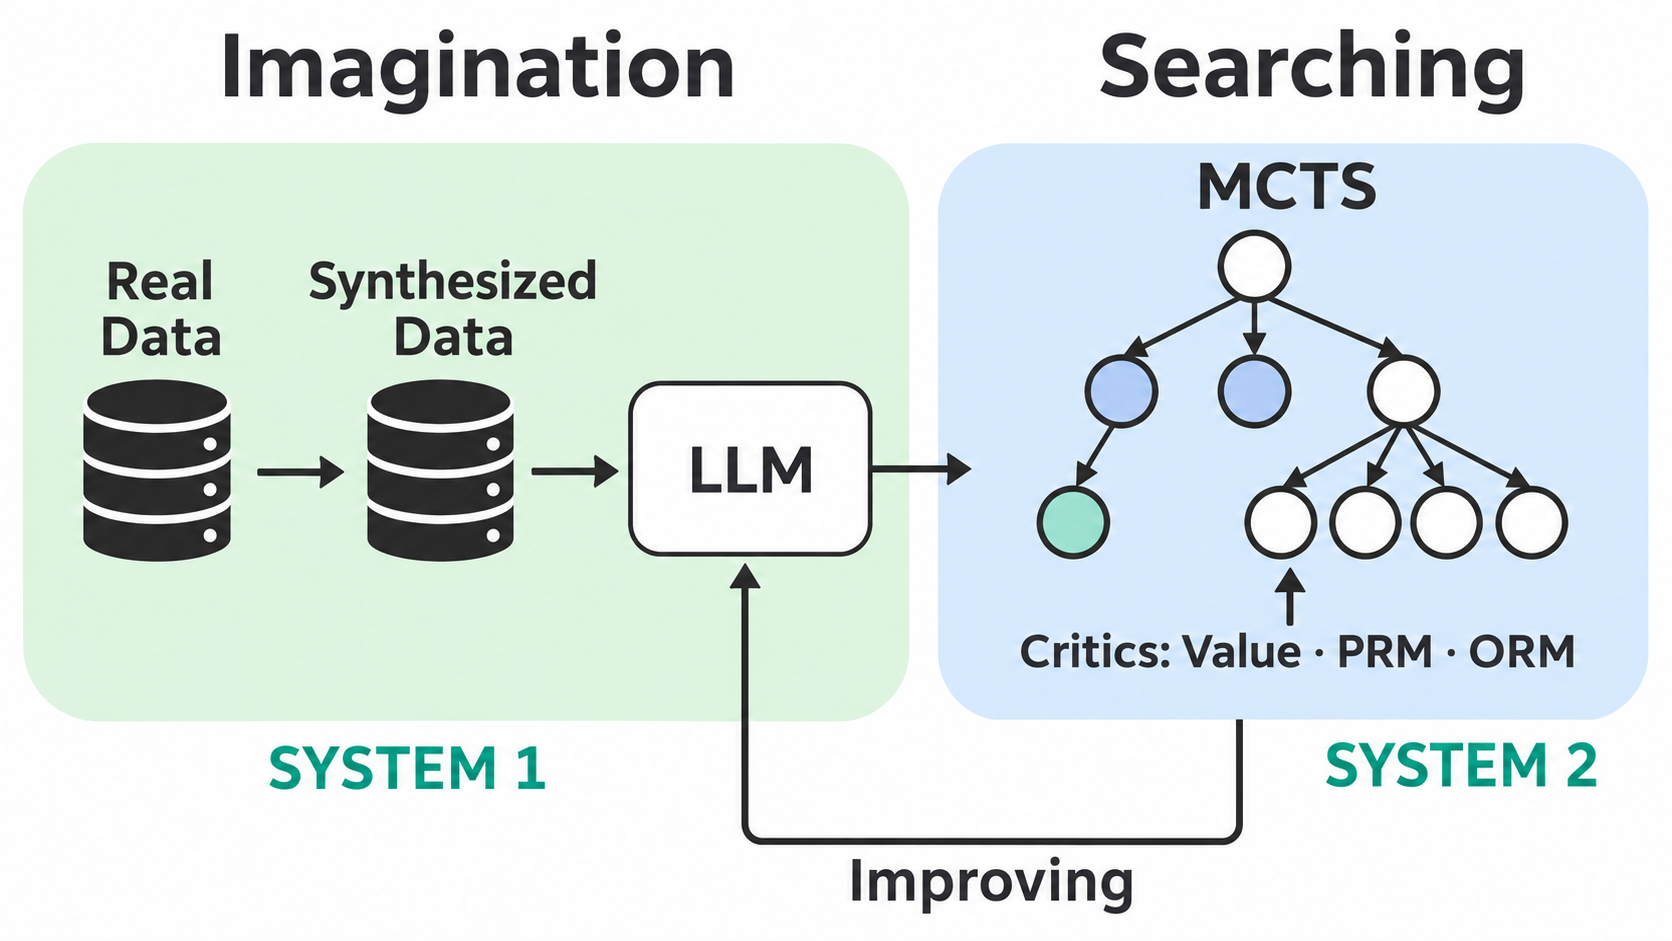
We proposed AlphaLLM, a self-improvement framework combining problem synthesis, self-training, MCTS, and multi-critic evaluation to iteratively improve mathematical reasoning through search and feedback. With tree search, the models achieved results comparable to contemporaneous GPT-4 in the paper’s evaluations. Published at NeurIPS 2024, the work ranked #1 on Hugging Face Daily Papers on April 19, 2024.
-
Tencent Jueyi (LuckyJ): large-scale self-play and multi-agent RL
Tencent AI Lab (AIPD)
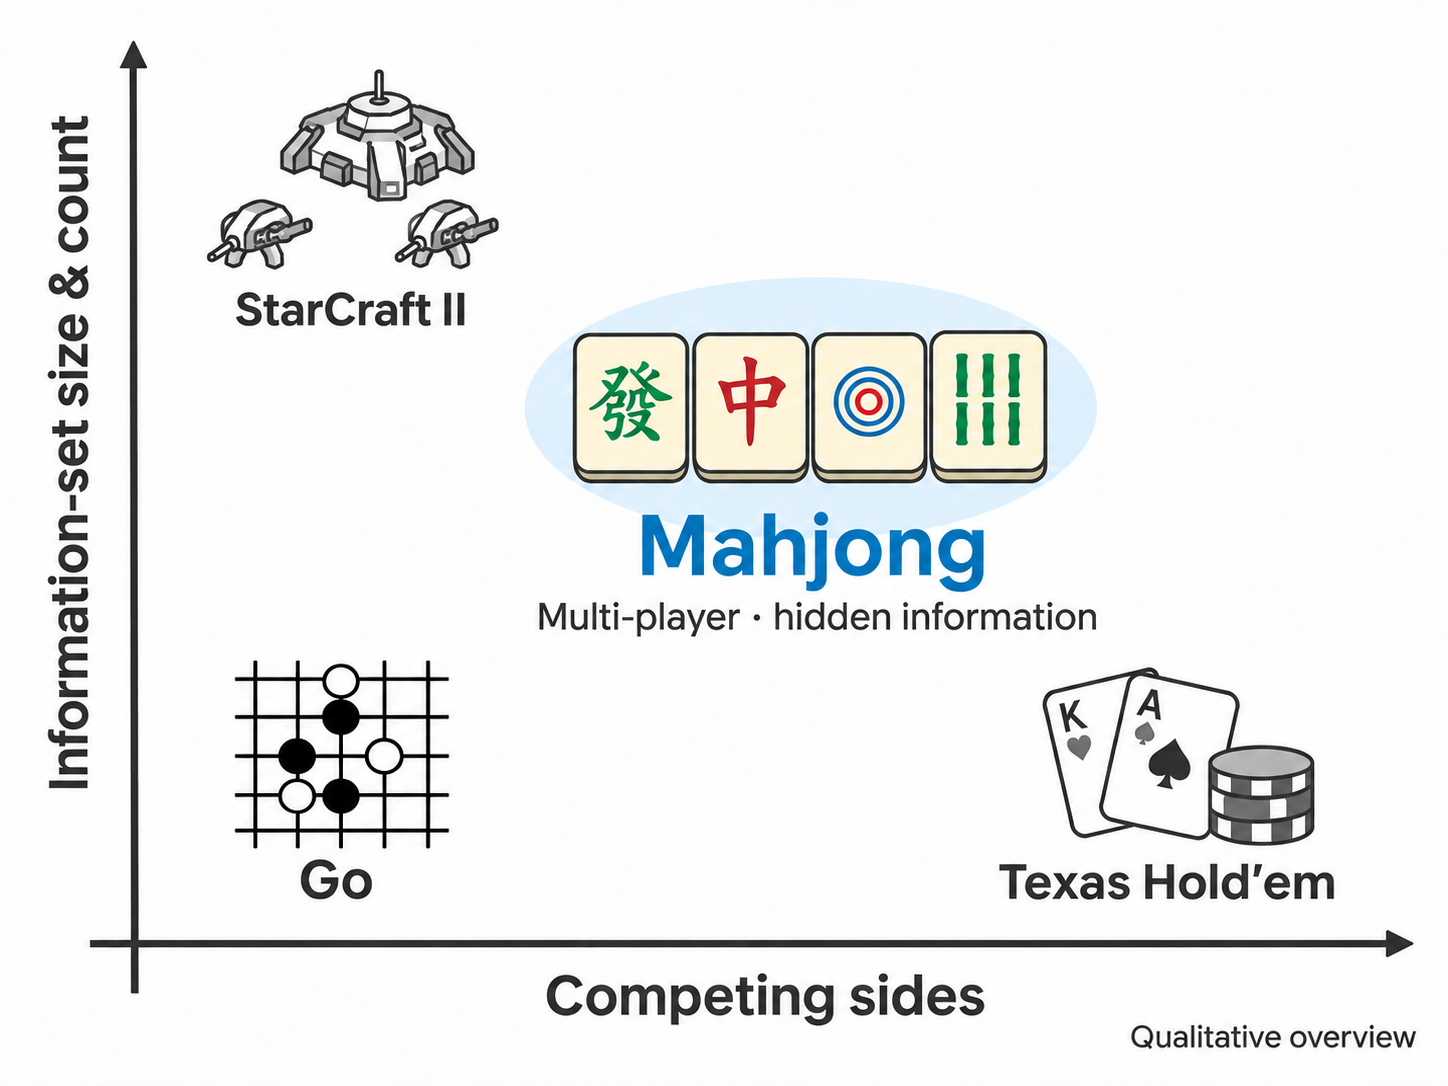
I worked on large-scale self-play reinforcement learning for imperfect-information games, training Tencent’s LuckyJ mahjong AI. LuckyJ outperformed a field of professional players that included a world champion, and set an all-time stable-dan record on Tenhou’s Tokujō tables in 2023.
In related research on opponent modeling and robust decision-making, we proposed GSCU, which combines opponent policy representations, online posterior inference, and policy switching to compete against unknown and nonstationary opponents. The work appeared at ICML 2022 (Spotlight).
Selected Publications
-
FLARE: A Failure-Aware Framework for Autonomous Correction and Recovery in Visual-Language Robotic Manipulation
CVPR 2026.
-
ProAct: A Benchmark and Multimodal Framework for Structure-Aware Proactive Response
ICML 2026.
-
Iterative Nash Policy Optimization: Aligning LLMs with General Preferences via No-Regret Learning
ICLR 2025 (Oral).
-
Multi-Agent Collaboration via Evolving Orchestration
NeurIPS 2025. [Code]
-
LiteSearch: Efficient Tree Search with Dynamic Exploration Budget for Math Reasoning
AAAI 2025.
-
TAIROS: An Embodied AI Platform for Robotics Applications
Technical report, 2025.
-
Toward Self-Improvement of LLMs via Imagination, Searching, and Criticizing
NeurIPS 2024. [Code]
-
Greedy when Sure and Conservative when Uncertain about the Opponents
ICML 2022 (Spotlight). [Code]